Artificial Analysis launches AA-3D, a human-judged benchmark for interactive 3D scenes
In brief
- Artificial Analysis announced the AA-3D benchmark on 12 October 2026, Crypto Briefing reported.
- AI models turn text briefs into working three.js scenes that run in an offline sandbox.
- Blind pairwise human votes feed an Elo-style ranking.
- Methodology details, prompt-set size and results have not been published yet.
How AA-3D works
Every test starts with a text brief. Under AA-3D, a model gets a written description of a scene and has to produce a functional three.js experience from it. (three.js is a JavaScript library used to render 3D graphics in a web browser.) Those outputs then run in an offline sandbox environment.
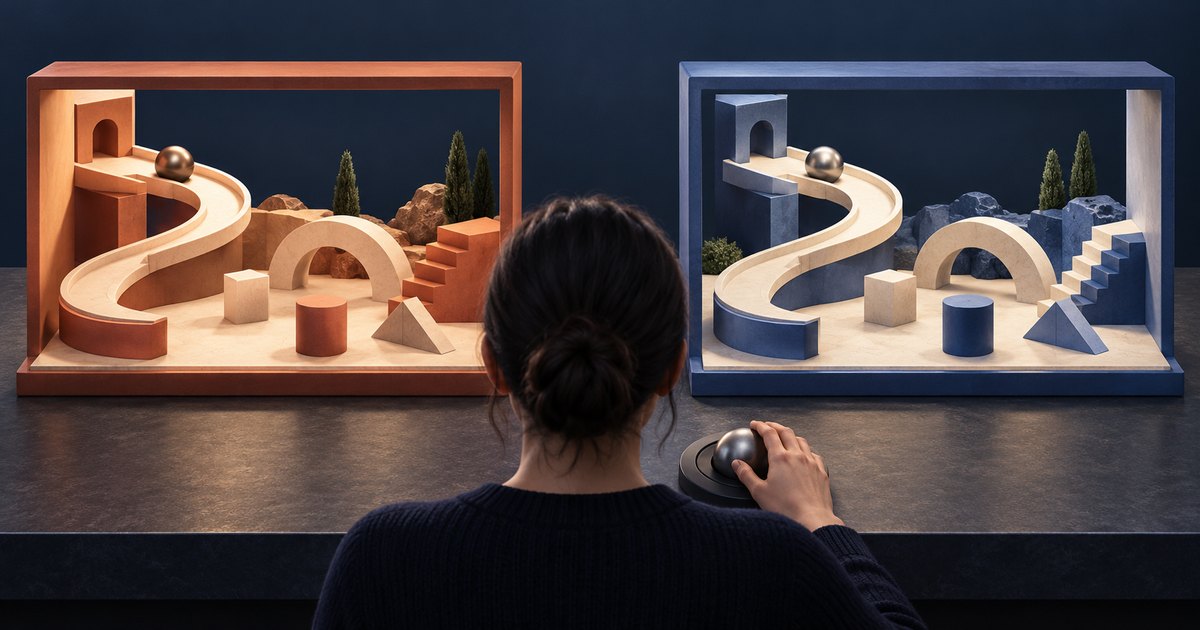
Humans do the judging. A recruited panel casts blind pairwise preference votes, viewing two outputs side by side without knowing which model built which, and those head-to-head results feed an Elo-style ranking. Crypto Briefing said the setup blends coding ability, spatial reasoning and visual judgment into a single score.
What hasn't been published
There's no leaderboard yet.
As of the announcement, no public details were available on AA-3D's methodology, prompt-set size or results. That means nobody can say which models lead.
The human-preference format isn't new for the firm, though. Its most recent example, AA-Video-T2V v2.0, launched around 30 September 2026, and Crypto Briefing reported that the text-to-video benchmark drew more than 68,000 votes across 1,000 prompts.
Where it fits, and the trade-off
AA-3D isn't the first attempt to test 3D generation. Crypto Briefing noted that academic and community projects such as T3Bench and Blender AI Arena already assess text-to-3D tasks, but they focus on broader text-to-3D generation and static 3D assets. AA-3D looks only at interactive three.js outputs.
The outlet also weighed the voting model. In its view, blind pairwise voting is harder to optimize against than automated metrics because the target is subjective human judgment. The catch, Crypto Briefing said, is that preference votes reflect the tastes of whoever sits on the panel, and how that panel's assembled could influence which models rank highest.
Panel makeup is part of the methodology, and that hasn't been published yet.
Frequently asked questions
How does the AA-3D benchmark test AI models?
Each model gets a text brief describing a scene and has to produce a functional three.js experience from it. Those outputs run in an offline sandbox. A recruited panel then casts blind pairwise votes, and the results feed an Elo-style ranking.
Which AI models rank highest on AA-3D?
That isn't known yet. As of the announcement, no public details were available on AA-3D's methodology, prompt-set size or results, according to Crypto Briefing.
How is AA-3D different from T3Bench or Blender AI Arena?
Crypto Briefing said T3Bench and Blender AI Arena already assess text-to-3D tasks, but they focus on broader text-to-3D generation and static 3D assets. AA-3D looks only at interactive three.js outputs.